Cut LLM Costs with Caching
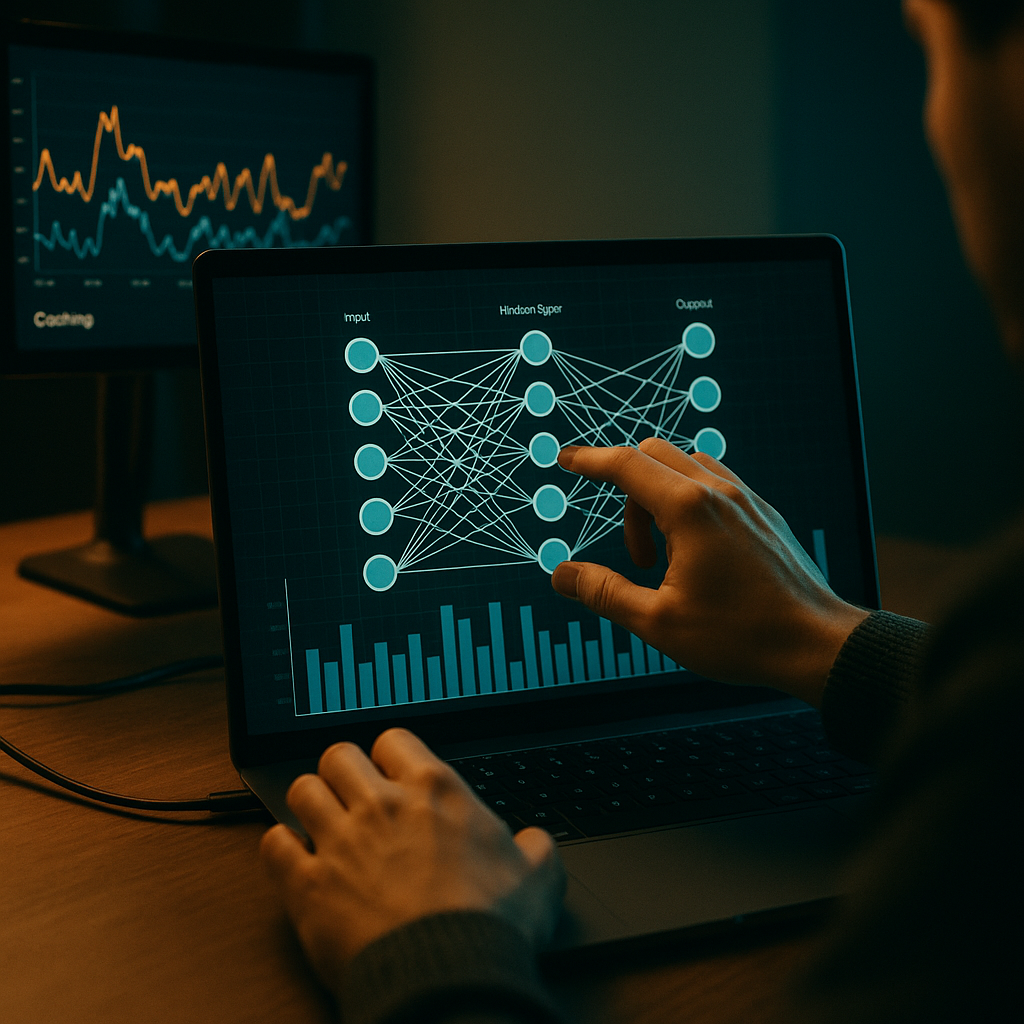
In the rapidly evolving world of Artificial Intelligence, Large Language Models (LLMs) have become invaluable tools for businesses. However, the cost of using these models can escalate quickly, especially when they are asked the same questions repeatedly. A recent article from The New Stack highlights how an age-old caching technique can significantly reduce these costs.
Understanding the Cost Implications
Every time an LLM processes a query, it incurs costs. This is particularly evident when users repeatedly ask similar or identical questions. The financial burden can accumulate, leading to unexpected expenses in operational budgets. For organizations leveraging LLMs for customer service, content generation, or data analysis, this can become a pressing issue.
The Power of Caching
Caching is a technique that stores the results of expensive function calls and returns the cached result when the same inputs occur again. By implementing caching for LLM responses, businesses can:
- Reduce redundant processing, thereby lowering costs.
- Improve response times by serving cached results.
- Enhance user experience through quicker interactions.
Implementing Caching Strategies
To effectively implement caching for LLM responses, consider the following strategies:
- Identify Frequent Queries: Monitor user queries to determine which questions are asked most often.
- Set a Cache Expiration: Determine how long responses should remain cached to ensure information remains relevant.
- Utilize a Cache Layer: Implement a dedicated caching layer that interfaces with your LLM, storing and retrieving responses efficiently.
Why This Matters
Adopting a caching strategy not only helps in managing costs but also optimizes the overall performance of LLMs. In an era where businesses are striving for efficiency and cost-effectiveness, this approach can be a game-changer.
Practical Takeaways
As organizations continue to integrate AI into their operations, understanding and implementing effective caching strategies can lead to:
- Significant cost savings.
- Enhanced operational efficiency.
- A better user experience through faster response times.
In conclusion, leveraging caching is a straightforward yet powerful way to reduce LLM costs and improve service delivery. For businesses looking to implement AI solutions effectively, BlockNova offers a range of services including AI consulting, AI agent architecture, self-hosted LLM/AI agent hosting, and server hosting. Let’s optimize your AI strategy together!
Source: Why an old caching trick is your secret to lower LLM costs
0 Comments